
Redact personal data before it leaves your perimeter, not after. The safest architecture for chat and LLM pipelines strips names, account numbers and identifiers at the proxy or middleware layer, before a single token reaches a third-party model, and pairs that with layered detection combining rules and machine learning. Every masking decision needs an auditable log entry, because that record is what satisfies pseudonymisation and data minimisation expectations under GDPR and the NIST Privacy Framework.
TL;DR:
- Redaction should occur at the proxy or middleware layer before data reaches third-party models to maximize privacy and meet GDPR and NIST standards.
- Detection methods combine regex for structured data and machine learning-based NER models to identify a wide range of PII, with confidence thresholds guiding automation or human review.
- Redaction practices must cover all touchpoints, including live chat, stored transcripts, and historical data, requiring layered defenses in hybrid architectures.
- Masking strategies vary from character replacements to synthetic data generation, and policies should prioritize data minimization while maintaining conversation clarity.
- Complete audit logs and strict redaction controls are essential for compliance audits and reducing risks in regulated markets such as gaming and healthcare.
Table of Contents
- What PII redaction for chat actually covers
- Detection methods: regex, NER, heuristics and hybrid approaches
- Where should redaction actually run?
- Masking strategies and redaction policies to codify
- Mapping redaction controls to GDPR Article 32 and NIST
- Testing, monitoring and audit trails that actually hold up
- Why human review still catches what automation misses
- How Pitbot builds redaction and oversight into everyday support
- Sources
- FAQ
What PII redaction for chat actually covers
PII redaction for chat means detecting and masking personal identifiers inside conversational data before it’s stored, forwarded to a model, or handed to a human reviewer. That includes live chat text, support transcripts, attached documents, and even transcribed audio segments from voice-to-chat handoffs.
The scope is wider than most teams assume. It’s not just live agent chat: retrieval-augmented generation (RAG) pipelines pull historical transcripts into context windows, multi-hop agents pass conversation state between tools, and archived transcripts sit in storage for months. Each of those touchpoints needs redaction coverage, not just the front door.
Entities that typically require masking include:
- Full names and usernames tied to real identities
- Email addresses and phone numbers
- Account IDs, loyalty numbers and internal customer references
- Payment card fragments (even partial numbers count)
- National ID numbers, passport numbers and tax identifiers
- Health-related identifiers or anything implying a medical condition
Detection methods: regex, NER, heuristics and hybrid approaches
Regex still does the heavy lifting for structured patterns. Card numbers, IBANs, national ID formats and email addresses follow predictable shapes, so regular expressions catch them fast and cheaply, with fully transparent logic you can audit line by line. The weakness shows up the moment PII gets messy: a name typed without capitals, an address split across three chat bubbles, a phone number written with words instead of digits.
That’s where named-entity recognition (NER) earns its place. Transformer-based or fine-tuned NER models read context rather than just character shapes, so they catch “my son’s account, it’s under Dave” as a name reference even without a pattern match. The cost is real: you need labelled training data reflecting your own chat traffic, and ongoing monitoring to catch model drift.
Most production systems end up hybrid: regex for structured formats, NER for free text, and an allowlist that excludes known non-PII terms (product codes, internal jargon) so the system doesn’t over-redact.
Confidence thresholds decide what happens at the margins. A detection above 0.9 confidence might auto-mask; anything between 0.5 and 0.9 could route to human review; below that, log it but leave the text untouched pending a wider policy review.
Pro Tip: Tune thresholds separately for regulated fields (payment data, national IDs) versus soft PII like first names. Treating them the same either buries reviewers in low-risk flags or lets high-risk data slip through.

Where should redaction actually run?
Placement determines whether raw PII ever leaves your control. Four architectures cover most real deployments:
- Proxy or middleware, redact-before-send. Redaction happens inside your network perimeter before the payload reaches a third-party model. This is the strongest privacy posture because raw PII never crosses the boundary, but it demands a secure detokenisation path so agents and reviewers can see restored values when they genuinely need to. Engineering guidance from Philterd treats this as the default for chat and RAG pipelines specifically because it prevents exposure at the source, not after the fact.
- In-flight masking at the agent interface. Useful for shaping what a human agent sees in real time, but masking at the UI layer doesn’t guarantee the raw data was ever stripped from logs, backend storage, or the client device rendering the chat window.
- Post-processing redaction. Applied to archived transcripts after the conversation has ended. Fine for compliance housekeeping and long-term storage, but useless as a control against model exposure, because the damage (if any) already happened during the live exchange.
- Hybrid deployment. In-flight masking protects agent UX and reduces what’s visible on screen, while proxy-level redaction handles anything destined for an external model call. Most regulated operators land here, because no single layer covers every risk on its own.
Masking strategies and redaction policies to codify
Pick a masking style deliberately, not by default. Vendor implementations such as Microsoft’s conversation PII redaction support several policies worth borrowing even outside that specific stack:
- Character mask — replaces detected text with a fixed character (e.g. “XXXX”), simple and fast, but destroys any downstream analytics value.
- Entity mask — replaces the value with its entity type (“[NAME]”, “[PHONE]”), preserving sentence structure for context-aware model responses.
- Synthetic replacement — swaps real values for plausible fake ones, letting a model reason over realistic-looking data without ever seeing the truth.
- No mask, log only — flags the entity without altering the text, appropriate only for low-risk internal audit contexts.
Value-exclusion lists and entity synonyms matter more than teams expect. A casino operator’s chat is full of numeric strings that look like account IDs but are actually promo codes or game reference numbers, and over-redacting those breaks the conversation’s meaning.
Pro Tip: If you ever need to restore original values, use short-lived token stores with strict TTLs, not permanent lookup tables. A detokenisation event should always generate its own audit entry, separate from the original redaction log.
Mapping redaction controls to GDPR Article 32 and NIST
GDPR Article 32 requires controllers and processors to implement measures like pseudonymisation and encryption, weighed against the state of the art and cost of implementation. Redact-before-send architecture is a direct, practical answer to that requirement, not a bolt-on.
The NIST Privacy Framework frames redaction as one form of disassociated processing, sitting alongside data minimisation and risk profiling as core privacy controls. NIST’s own guidance also recommends using Profiles to compare current and target privacy states, which gives compliance teams a structured way to prioritise where redaction investment goes first.
Keep these artefacts on hand for any audit:
- Redaction logs showing what was masked, when, and under which policy
- Processing records mapping data flows through chat, RAG and agent systems
- Detokenisation event logs, kept separate from the original masking record
- A documented breach notification path in case redaction fails silently
Testing, monitoring and audit trails that actually hold up
Precision, recall and F1 score are the baseline metrics, but the operational threshold matters more than the raw number.
| Metric | What it measures | Why it matters for chat |
|---|---|---|
| Precision | Share of flagged items that are genuinely PII | Low precision floods reviewers with false positives |
| Recall | Share of actual PII correctly caught | Low recall means real data leaks through undetected |
| F1 score | Balance of precision and recall | Single number for tuning threshold trade-offs |
| False positive rate | Non-PII incorrectly masked | High rate degrades chat readability and analytics value |
Build synthetic test datasets rather than mining real transcripts for edge cases; it avoids handling live PII just to test the system meant to protect it. Monitor for drift as new slang, product names or ID formats appear, and route uncertain cases into a human reviewer feedback loop rather than silently auto-approving them.
Why human review still catches what automation misses
Automated detection is necessary but never sufficient on its own. Rules miss novel phrasing; models drift as chat language evolves; edge cases pile up exactly where regulated markets can least afford them. The right operational posture is redact-before-send, conservative confidence thresholds, and a full audit trail behind every decision.
A successful approach reflects that priority: multi-provider AI drafts the response, personal data is masked before it reaches the model, a person can approve the reply before it reaches a player, and every decision is logged. In regulated markets, that combination of speed and oversight is what keeps compliance defensible.
— Pitbot
How Pitbot builds redaction and oversight into everyday support
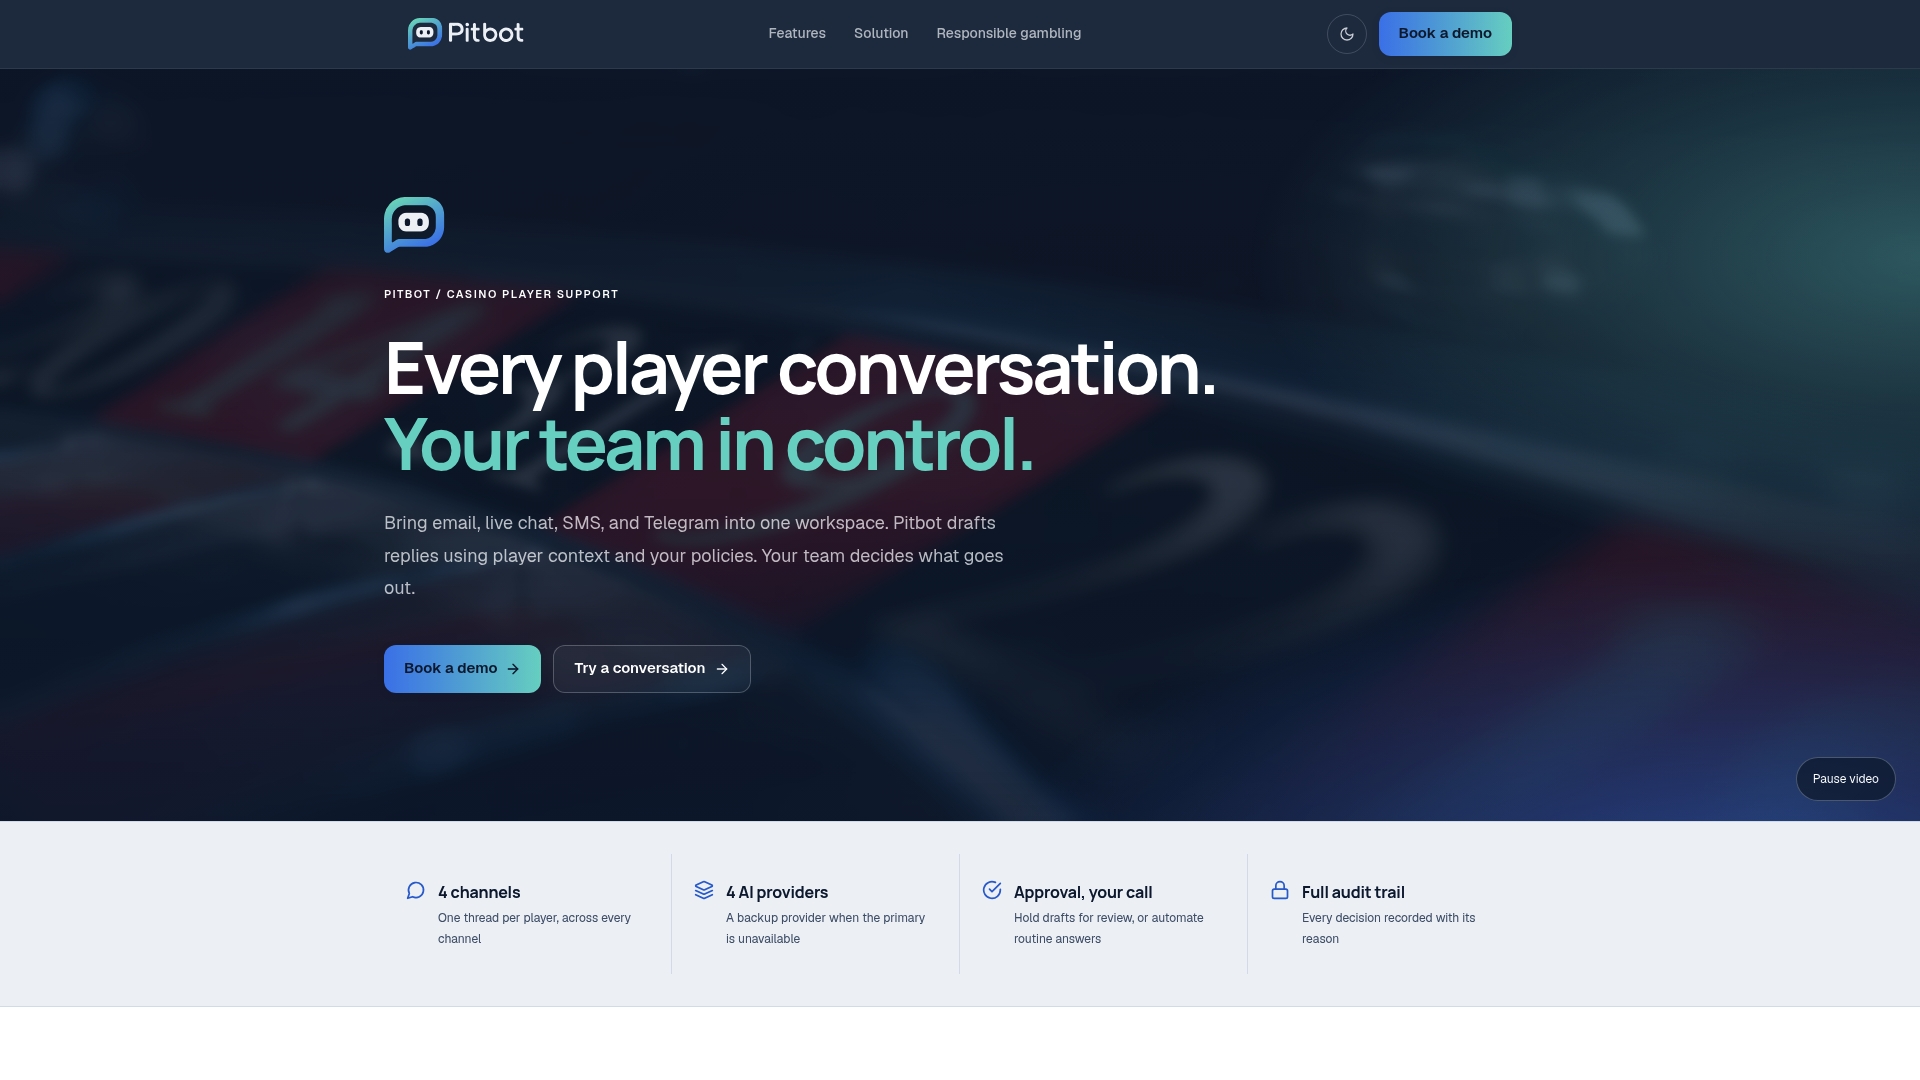
This solution offers an alternative to running your own detection stack from scratch for casino and iGaming operators who need player support that’s fast without cutting corners on compliance. Pitbot pseudonymises player personal data before a prompt reaches an AI provider, withholds account data from contacts whose identity is not verified, and checks AI output for personal data before it can be sent. With auto send off, AI-drafted replies on email, live chat and Telegram wait for staff approval before they reach a player, and every AI decision is recorded in an append-only audit trail. That oversight sits alongside multi-provider AI, omni-channel coverage across email, live chat, SMS and Telegram, and responsible-gambling detection with outreach suppression built into the same dashboard.
That matters because chat data in regulated markets carries real regulatory weight; a missed redaction or an unreviewed reply isn’t just a support hiccup, it’s an audit finding waiting to happen. Pitbot’s feature set bundles the audit trails, VIP-aware replies and multilingual support operators need without stitching together separate tools. If your team handles player conversations across regulated markets, see how the platform supports casino and iGaming support workflows or book a demo to walk through your specific compliance requirements.
Sources
For the legal text itself, read GDPR Article 32 directly rather than relying on summaries. The NIST Privacy Framework PDF covers risk profiling in full. For vendor-specific API behaviour, Microsoft’s conversation PII redaction documentation shows real configuration parameters, and Philterd’s engineering guide to redacting PII before an LLM call walks through the redact-before-send pattern in practical detail.
- Regulation (EU) 2016/679 (General Data Protection Regulation)
- NIST Privacy Framework
- How to Redact PII Before Sending to an LLM: Chat, RAG, and AI Agents — Philterd
FAQ
What PII needs to be redacted in chat data?
Names, email addresses, phone numbers, account IDs, payment card fragments, national ID numbers and any health-related identifiers all need redaction before they reach a third-party model or long-term storage. The exact list should be defined in your redaction policy and mapped against your GDPR Article 32 obligations.
What is PII redaction?
PII redaction is the process of detecting and masking personally identifiable information in text, audio or documents so the underlying data can’t be read or reconstructed by unauthorised systems or people. In chat pipelines, that usually means masking before the text is sent to an AI model, with a secure path to restore values only for authorised human review.
What are five examples of PII?
Common examples include a person’s full name, email address, phone number, national ID or passport number, and payment card details. Health identifiers and precise location data also count as PII in most regulatory frameworks, including under GDPR.
What is PII detection in AI?
PII detection in AI uses techniques like regex pattern matching, named-entity recognition and confidence-scored heuristics to automatically flag personal identifiers within text or speech. Systems such as Microsoft’s conversation PII detection combine these methods and return both redacted text and metadata about what was found.
Does Pitbot redact PII before AI responses reach players?
Yes. Pitbot pseudonymises player personal data before a prompt reaches an AI provider and checks AI output for personal data before it can be sent. You can also hold AI-drafted replies for staff approval before they reach a player, and every AI decision is recorded in an append-only audit trail. Full platform capabilities are detailed on the Pitbot features page.